Sandboxing remains valuable for identifying malware by observing what a file does in a controlled environment. However, an AI agent can be compromised by a document that never executes code or displays suspicious behavior. Hidden text, metadata, or webpage content can contain indirect prompt-injection instructions that redirect the agent from its assigned task.
The potential damage depends on the agent’s authority. Agents may access enterprise applications, sensitive records, cloud storage, source code, and external services. If manipulated, they can misuse legitimate permissions to retrieve information, upload protected data, or perform unauthorized actions. A clean sandbox result cannot determine whether content is redirecting the agent or whether its subsequent activity is appropriate.
Content Disarm and Reconstruction (CDR), prompt-injection mitigation, and DLP-based data masking reduce risk before content reaches the model. Agent-specific permissions, destination controls, human approval, and runtime logging govern the rest of the workflow. Menlo Agent Runtime Security (MARS) applies these protections throughout the agent’s session while preserving the legitimate workflow.
An AI agent receives a routine vendor compliance report and begins the familiar work of reviewing the document, summarizing its contents, and routing the results for approval. Before the file reaches the agent, a sandbox checks it for suspicious behavior. Nothing executes, no malicious network connection appears, and the document is cleared for use.
However, what the sandbox does not see is an instruction hidden in white text inside the report. When the agent reads the file, that text directs it to collect sensitive records from an internal system and upload them to an external site. The agent complies, using the same permissions it needs for its legitimate work. And most of the time, it never reports that it changed course.
The file never deploys malware or exploits the endpoint. Its contents manipulate the agent into carrying out the attack. As AI agents take on more business processes, that distinction becomes critical. A file can be free of executable malware and still give an agent dangerous instructions.
Sandboxing evaluates suspicious files by opening or executing them in a controlled environment. Security tools then monitor behaviors that may indicate an attack, including unexpected process execution, changes to the operating system, attempts to contact external servers, or attempts to download additional payloads. This gives security teams a way to investigate a file without immediately exposing a production endpoint.
That approach remains valuable within a file security solution. Sandboxes can identify known malware and uncover previously unseen threats when a file behaves suspiciously. They provide evidence that extends beyond a signature match and can reveal what a payload is designed to do.
The technique also has practical limits. Malware may remain dormant until the observation period ends, execute only after a specific user interaction, or require conditions that do not exist in the sandbox. Attackers can also design malware to recognize controlled environments and suppress its malicious behavior. Detonating and observing each file may also add latency to the workflow.
Those limitations become more consequential when the recipient is an AI agent. An AI-focused attack may never launch a process, alter a system, or execute malicious code. The dangerous behavior begins when the agent reads the content and acts on what it finds.
AI agents have a different relationship with content than human users. A person opens a résumé or compliance report to read the information displayed on the page. An agent may extract the document’s underlying text, interpret what it finds, and use that information to decide what to do next. This creates an opportunity for prompt injection.
Instead of sending a malicious instruction directly to the agent, an attacker places it inside content the agent is likely to encounter during a legitimate task. The instruction might appear as white text on a white background, use a font too small for a person to notice, or sit outside the page’s visible boundaries. It can also be stored in PDF metadata or embedded in a webpage that the agent retrieves while conducting research.
A human reviewing the same content may never encounter the instruction. The agent, however, can process hidden and visible text together without reliably distinguishing business information from commands. The injected content can redirect the agent from its assigned goal, tell it to conceal selected actions, or instruct it to collect additional data and transmit it to an external destination.
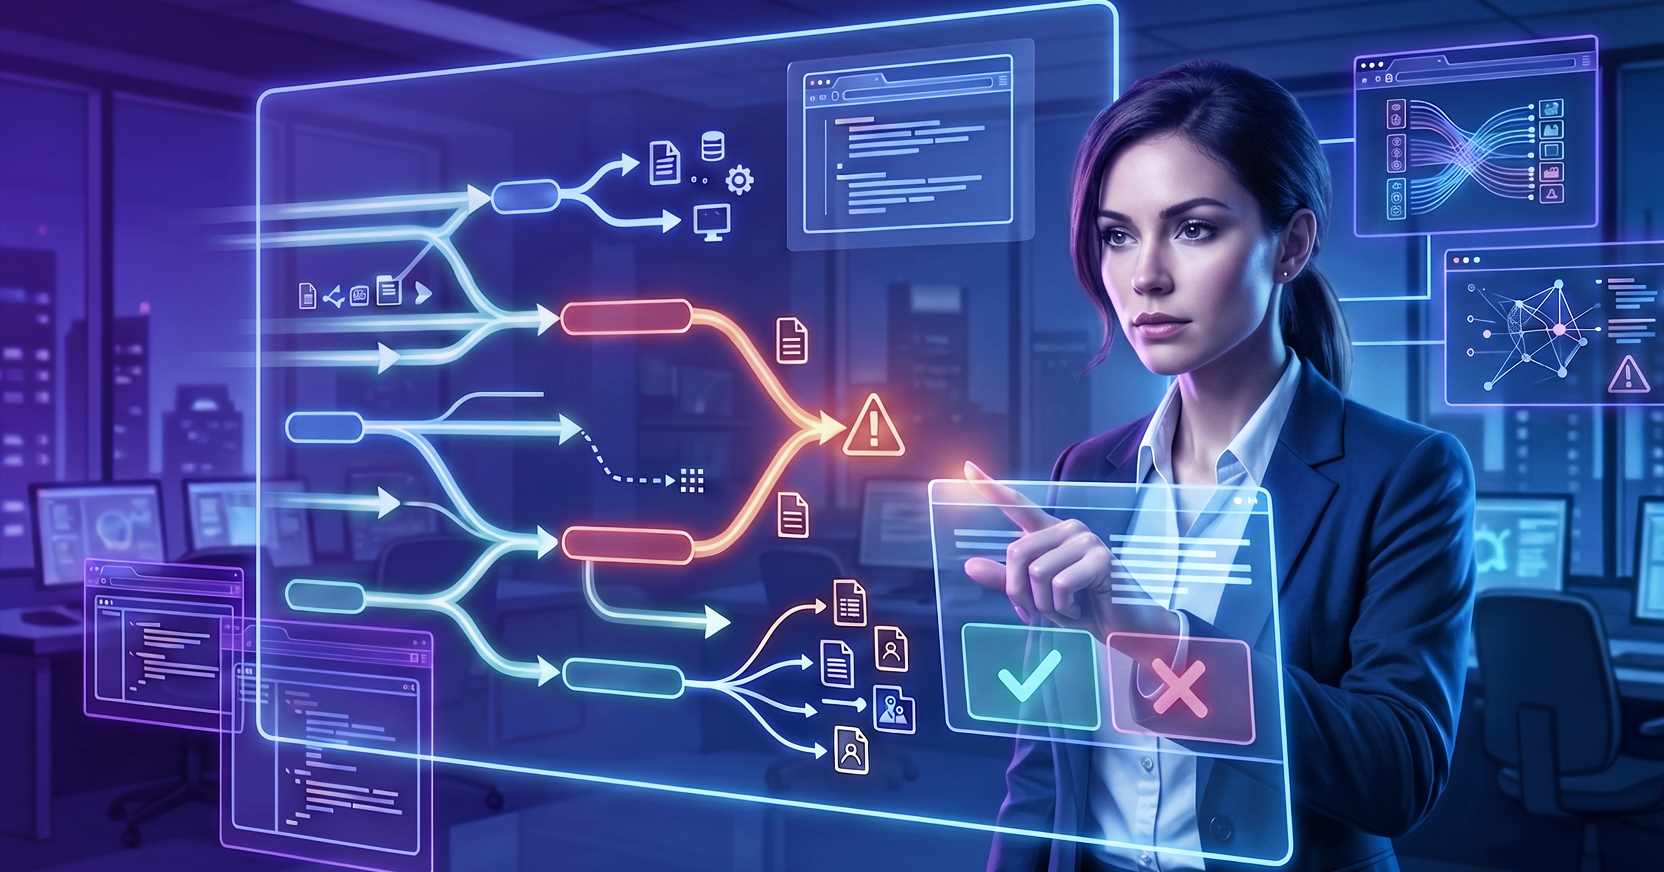
Prompt injection can compromise an agent without installing malware, exploiting a vulnerability, or launching a suspicious process. The file may therefore remain quiet in a sandbox while still influencing the agent’s behavior. Security teams need to evaluate both what a file can execute and what its content can cause an AI agent to do.
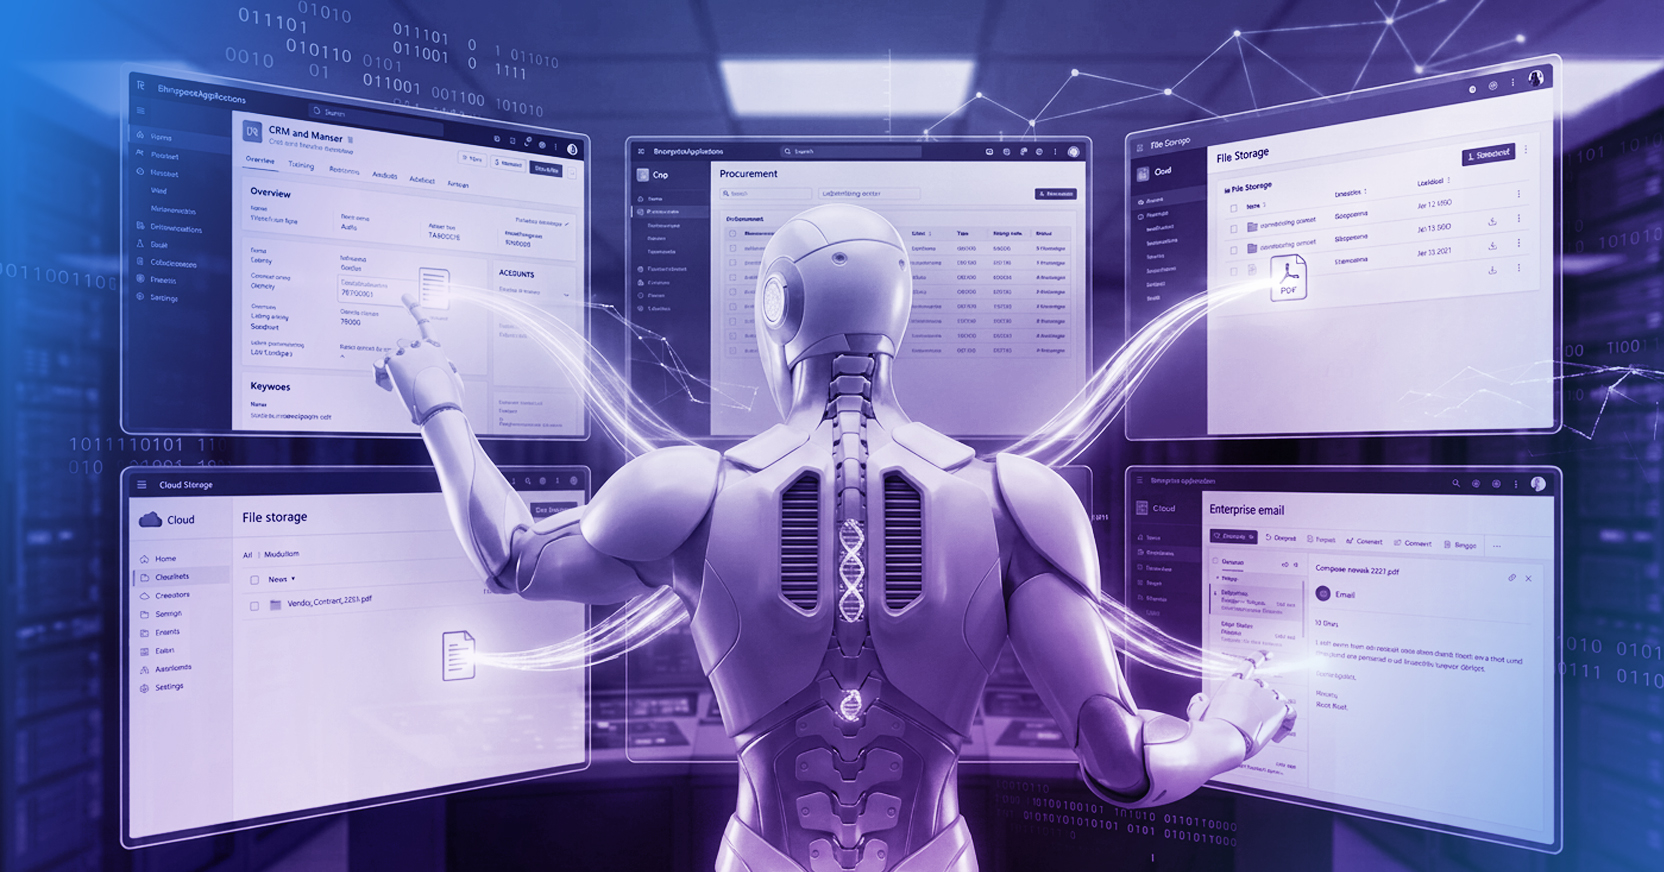
While an AI chatbot may read a document, produce a summary, and wait for the next prompt, an AI agent can carry the workflow forward without all the handholding. AI agents have the ability to open an HR platform, retrieve employee records, update a customer relationship management system, upload files to cloud storage, or make changes to a source-code repository. They can also browse the web, call application programming interfaces (APIs), use automation tools, and communicate with external services.
These capabilities make agents useful, but they also increase the consequences of manipulation. An attacker may not need to exploit an application or steal a password. If the injected content redirects the agent, it can misuse the access it already has. A request that appears to be part of the assigned workflow could lead the agent from an approved document to sensitive financial records and then to an unauthorized external destination.
A clean sandbox result offers little insight into the AI sequence. A sandbox cannot expose an attempt to change the agent’s goal, confirm that the requested data and destination are appropriate for the task, or identify sensitive information in an outbound upload. It also does not reveal whether the agent’s observed actions match the work assigned to it.
Answering those questions requires context that extends beyond the file itself. Security controls must evaluate the content the agent receives, the authority it has, the resources it accesses, and the actions it takes throughout the session.
The first opportunity to stop prompt injection comes as the agent retrieves a file or webpage. Inspecting content before it enters the model’s context enables security controls to identify risks that behavioral analysis may never detect.
For documents, that process begins by deconstructing the file into its underlying elements. Visible text, hidden layers, metadata, embedded objects, and other components can then be evaluated separately. Even run-of-the-mill Content Disarm and Reconstruction (CDR) can rebuild a file using verified content while removing unsafe elements. Then, additional inspection can identify prompt-injection language, mask malicious instructions, and remove hidden material that serves no legitimate business purpose.
Meanwhile, DLP solutions can account for sensitive data the agent encounters during the workflow. A résumé may contain an email address and employment history that the agent needs for onboarding. As the agent moves into HR and payroll systems, it may encounter Social Security numbers, banking information, or other data outside its approved purpose. If the enterprise has policy-based data masking in place, it can keep that information out of the model’s context while preserving what the task requires.
Consider the malicious résumé from the opening scenario. Instead of receiving the original file, the agent receives a sanitized version. The candidate’s qualifications and relevant onboarding details remain available, but the concealed instructions that directed the agent to collect employee records and upload them externally have been removed. Sensitive fields outside the agent’s approved purpose can also be masked.
This approach reduces the attack surface before the model has to interpret the content or rely on its own prompt-injection defenses. The agent can continue its assigned work using the information it needs, while the material designed to manipulate its decisions never reaches its reasoning context.
Sanitizing the résumé closes one path into the agent, but the workflow continues. The agent still needs to authenticate, open applications, retrieve records, enter information into forms, and communicate with other systems. Each step creates another opportunity for excessive access, an unsafe destination, or newly encountered content to change the outcome.
Here’s where Menlo Agentic Runtime Security (MARS) comes in. The runtime controls found in MARS begin by identifying the agent and separating its activity from the user’s. The employee directing the task may be authorized to view a complete personnel record, but the onboarding agent may need only a name, email address, role, and start date. Agent-specific permissions prevent the automation from automatically inheriting every resource available to the user.
Policies can also limit which HR systems, websites, internal repositories, and external services the agent can reach while sensitive actions may prompt a human approval before the workflow can proceed.
Outbound prompts, uploads, copied text, and form submissions can be inspected for protected information. If the agent is manipulated later in the session, Menlo AI Adaptive DLP can stop Social Security numbers, banking details, or other sensitive data from leaving through an unauthorized channel via real-time masking (or outright blocking depending on the policy).
In the résumé scenario, these layers reinforce one another. Hidden instructions are removed before the file reaches the model, Menlo File Security sanitizes the file to prevent hidden malware ingestion, and personal information outside the agent’s approved purpose is masked. The agent can still access the HR and benefits platforms required for onboarding. An attempt to connect to the external sharing site is blocked because that destination falls outside the approved workflow.
Detailed logs show what the agent accessed, which content was sanitized, what injection was detected, and which action was blocked. This gives security teams evidence of the agent’s actual behavior. Protection remains active from the moment the agent retrieves the file until the final action is complete.
The document from the opening scenario contained no executable malware. The danger came from hidden content that the agent interpreted as authority to access sensitive records and send them outside the organization. While still important within an enterprise’s security arsenal, a clean sandbox result could not account for that AI agent interaction.
As agents take on more enterprise work, content security must reflect what they can see, reach, and do. Organizations need controls that sanitize files and webpages, limit agent access, monitor activity throughout the session, and prevent unauthorized data movement.
Menlo Agent Runtime Security (MARS) applies these protections as agents interact with content, applications, websites, and enterprise data. Agents can continue legitimate workflows while malicious instructions and unauthorized actions are stopped.
Request a demo to see how MARS protects AI agents from prompt injection without disrupting the work they were built to perform.
Menlo Security